
An edge case in autonomous driving is a rare, unexpected scenario that falls outside the normal distribution of situations a perception or planning model has been trained on. Edge cases include unusual weather, atypical road users, sensor failures, novel object configurations, and ambiguous scenarios that require human-level reasoning. Handling them well is the difference between an autonomous system that performs in controlled testing and one that handles real-world deployment. Production AV teams address edge cases through targeted data collection, scenario-aware annotation guidelines, multi-sensor consistency checks, and dataset curation that intentionally over-samples the long tail.
Your autonomous driving model hits 99% accuracy on your test set. Then a truck carrying a mirror-wrapped art installation merges onto the highway, and your perception stack has no idea what it's looking at.
An edge case in autonomous driving is a rare, unexpected scenario that falls outside the normal distribution of situations a self-driving system was trained on. Edge cases include unusual weather conditions, rare road objects, unpredictable road user behavior, and sensor failures. They represent the "long tail" of driving scenarios and are the primary safety challenge for autonomous vehicle development.
This guide breaks down what edge cases are, why they matter so much for safety, the different types you need to plan for, and practical methods for detecting and handling them. Whether you are building an L2+ ADAS system or working toward full autonomy, this is the playbook for tackling the long tail.
Key Takeaways
- Edge cases are rare driving scenarios outside a model's training distribution, and they represent the primary safety challenge for autonomous vehicle development.
- A self-driving system that is right 99% of the time on routine driving can still fail on the rare scenarios it has barely seen, and those are the ones that matter most.
- The four main edge case categories are environmental (weather, lighting), object-level (rare objects), behavioral (unpredictable road users), and sensor-specific (hardware failures, blindspots).
- Detection methods include rule-based filtering, data-driven anomaly detection, and active learning loops that combine model uncertainty with human expertise.
- Research from NVIDIA's Alpamayo-R1 project showed that training with reasoning data led to up to a 12% improvement in planning accuracy on challenging cases and a 35% reduction in close encounters.
What Is an Edge Case in Autonomous Driving?
An edge case is any driving scenario that falls outside the normal distribution of situations your model was trained on. These are the rare, unusual, or unexpected events that a system encounters infrequently but must still handle correctly.
Think of it this way: the vast majority of driving is routine. Lane keeping on a clear highway. Following traffic at a signalised intersection. Parking in a well-marked lot. Your model sees thousands of hours of this kind of data and gets very good at it. But driving also includes a father chasing a ball into the street, a couch that fell off a moving truck, or a traffic cop waving you through a red light with hand signals your model has never encountered.
These are edge cases. And they matter far more than their frequency suggests.
The core challenge is what researchers call the long tail problem. In autonomous driving, the distribution of scenarios follows a power law. A small number of common scenarios account for most of your driving miles, while a vast number of rare scenarios each occur infrequently. The trouble is that safety-critical events cluster in that long tail. The scenarios your model has seen the least are often the ones where failure has the highest cost.
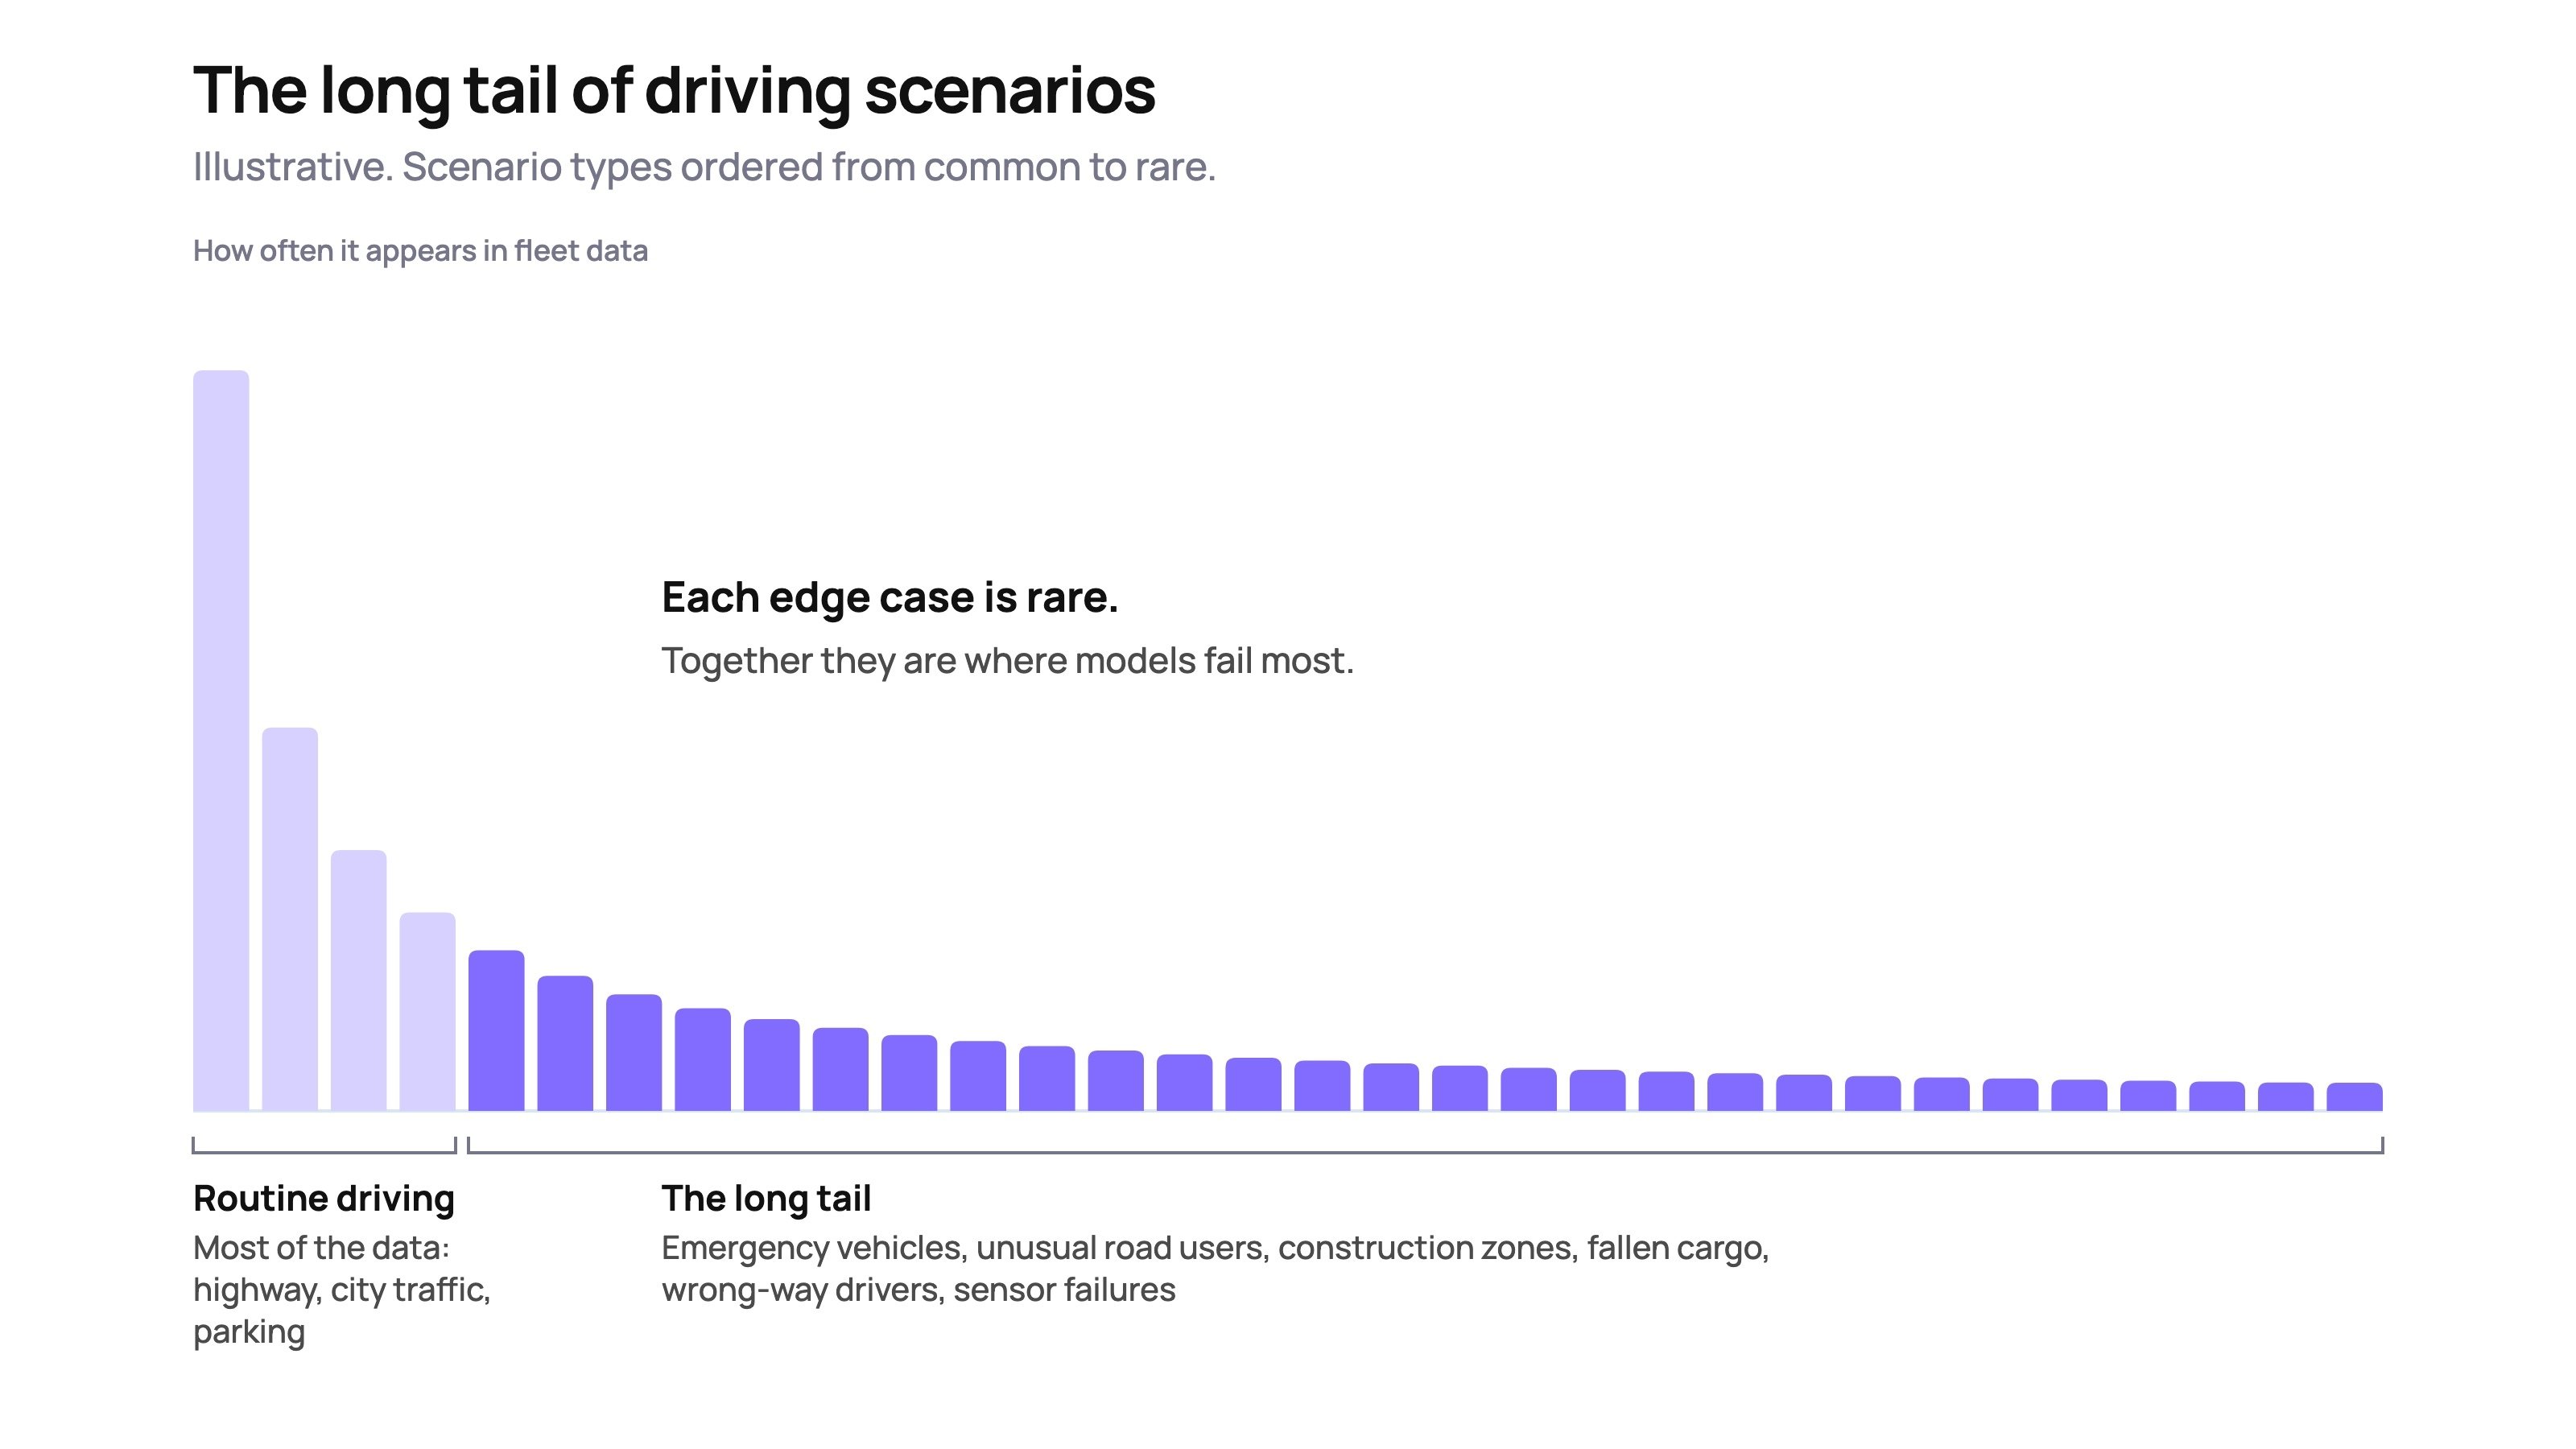
This is why a high average accuracy is not good enough. An accuracy figure measured mostly on routine driving says little about the long tail, and the long tail is where the costly failures sit.
Examples that illustrate the challenge:
- A pedestrian in a wheelchair crossing mid-block at night
- A cyclist riding the wrong way in a bike lane
- A fallen tree partially blocking your lane on a curve
- A construction zone with contradictory signage
- Sun glare reflecting off a building directly into your front-facing camera at the exact moment a pedestrian steps off the curb
Each of these is individually rare. Collectively, they represent the frontier of autonomous driving safety.
Why Do Edge Cases Matter for Autonomous Driving Safety?
Autonomous driving is a safety-critical application. Unlike a recommendation engine that suggests the wrong movie, an autonomous vehicle that mishandles an edge case can cause serious injury or death. The margin for error is effectively zero.
This reality is reflected in evolving regulatory frameworks. ISO 21448 (SOTIF, Safety of the Intended Functionality) specifically addresses hazards that arise not from system faults but from functional insufficiencies. In plain language: your system works exactly as designed, but its design does not account for a scenario it encounters in the real world. That is an edge case problem. SOTIF requires manufacturers to systematically identify and mitigate these scenarios.
The distinction between nominal scenarios and edge cases is critical for testing and validation. Nominal scenarios prove your system works under expected conditions. Edge cases prove it does not break under unexpected ones. Both are necessary, but edge case coverage is what separates a demo from a product.
From a machine learning perspective, edge cases represent distribution shift. Your model learns a mapping from input data to driving decisions based on its training distribution. When it encounters data that looks fundamentally different, its predictions become unreliable. The model does not know what it does not know.
What Are the Main Types of Edge Cases in Autonomous Driving?
Edge cases fall into distinct types, each presenting different challenges for perception, prediction, and planning.
Environmental Edge Cases
The driving environment itself can create scenarios that push perception systems beyond their comfort zone.
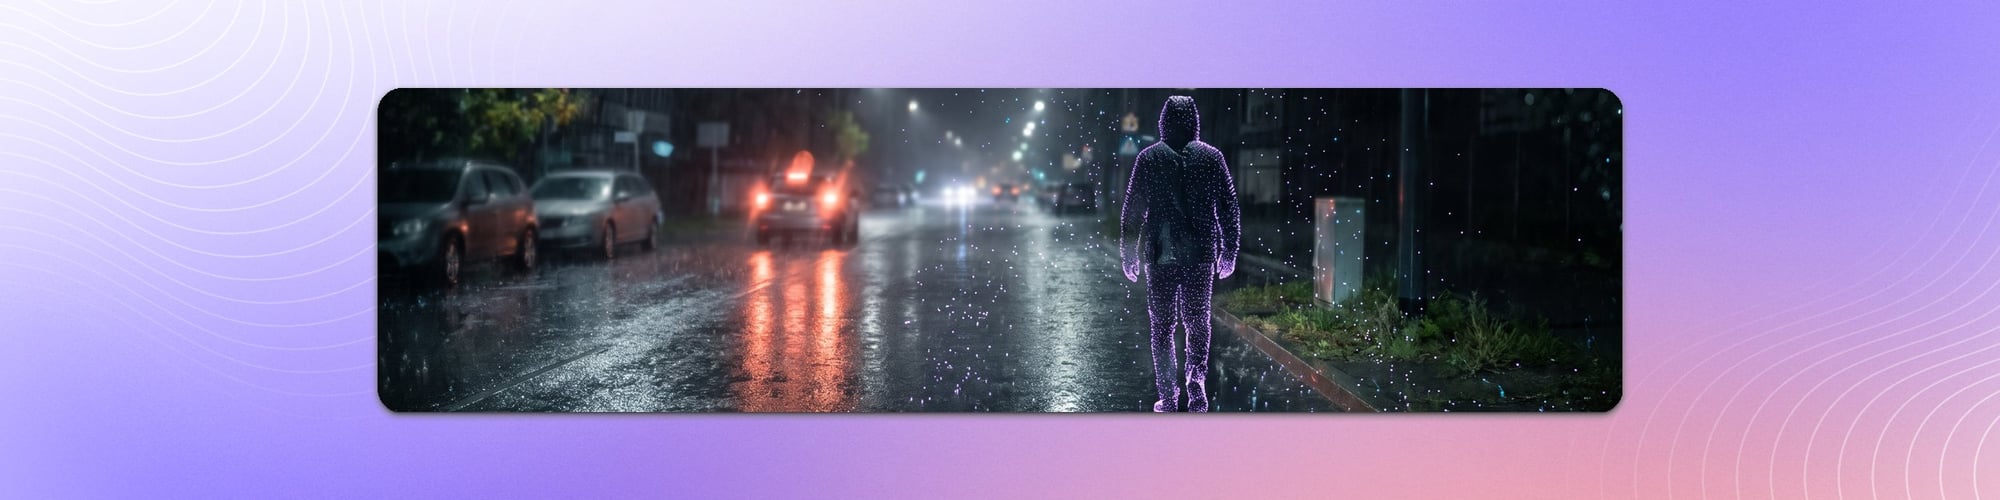
Extreme weather is the most obvious category, and the least rare. Any fleet that drives outside a desert collects thousands of hours of rain and darkness without trying. The difficulty is not finding weather data but labeling it consistently. In heavy rain at night, one annotator sees a pedestrian and another sees a reflection on wet asphalt, and both are being reasonable. A dataset can hold plenty of bad-weather volume and still teach the model an averaged rule that matches neither of them.
Each sensor degrades differently, so sensor fusion does not simply average the problem away. Rain scatters light on the camera lens and softens object edges exactly where precision matters, while raindrops and the spray thrown up behind a truck return LiDAR pulses as points floating in the air. Radar handles rain well but gives far less to pin an object down with. Settled snow changes the scene itself: lane markings and curbs disappear under one white surface, and the drivable area has to be inferred from tire tracks and other vehicles. Dense fog shortens the range of every sensor that relies on light.
Unusual lighting fails in a different way. At night the problem is absence rather than noise. LiDAR emits its own light and is largely indifferent to darkness, so a pedestrian at 60 meters can be a clear cluster in the point cloud and still be invisible in the camera image that would normally say what it is. That gap between camera and LiDAR is widest after dark. Low-angle sun produces long shadows that can be misread as objects, and reflections off wet roads create phantom detections.
The hardest moments are the transitions. Leaving a tunnel into low winter sun, the camera's auto-exposure needs a second or two to adapt. Glare off a wet road after a shower can saturate a sensor just as a pedestrian steps off the curb. These windows last seconds inside sequences that are otherwise clean, so frames sampled at fixed intervals tend to miss them, and most datasets hold far fewer of them than the fleet actually recorded.
Road surface conditions add another layer. Flooded road sections, black ice, oil spills, freshly paved surfaces with no markings, and active construction zones all change the assumptions your model makes about drivable area.
Object-Level Edge Cases
Rare objects are things your model may have never seen in training. An overturned semi-truck blocking three lanes. A mattress in the road. A horse and rider on a rural highway.
Unusual appearances of common objects are equally problematic. A vehicle wrapped in chrome. A flatbed truck carrying another car (is that one object or two?). A cyclist wearing a costume.
Ambiguous objects sit in the gray area. Is that dark shape on the road a plastic bag or a rock? Is that flash of movement a bird or a ball about to be followed by a child?
Behavioral Edge Cases
Unexpected traffic behavior includes wrong-way drivers, pedestrians jaywalking from behind parked vehicles, cyclists running red lights, and vehicles making illegal U-turns.
Cultural driving differences matter for any company deploying globally. Roundabout behavior varies dramatically between countries. The unwritten rules of merging, yielding, and right-of-way differ.
Emergency vehicles present a specific behavioral edge case. Sirens and flashing lights require specific responses that depend on local laws, direction of travel, and road geometry.
Sensor Edge Cases
LiDAR blindspots and reflections create gaps in 3D perception. Highly reflective surfaces can produce phantom points. Very dark surfaces may return no points at all.
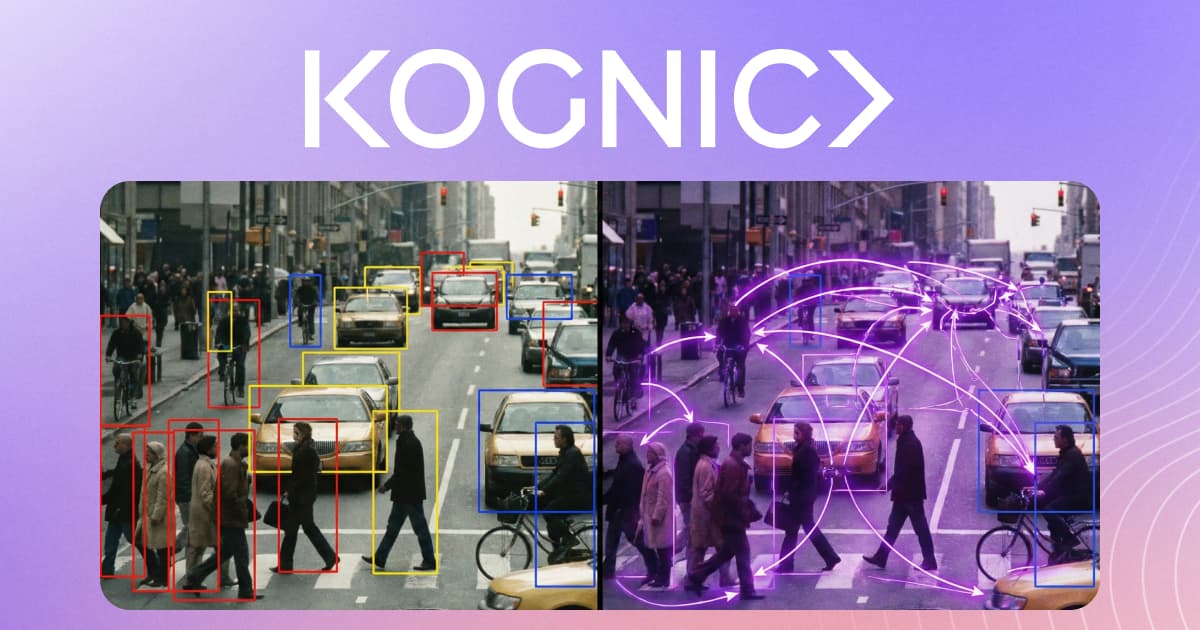
Sparse LiDAR returns make distant and small road users hard to find. A nearby car returns many points; a pedestrian or cyclist farther away may return only a few. Annotators handle this by highlighting the object in the camera image and projecting that region into the point cloud as a frustum, and by playing the LiDAR sequence as a video, where moving objects stand out even with few hits. Models can borrow the same tricks. When Kognic painted 2D camera detections onto LiDAR points in Zenseact's Edge AnnotationZ challenge, detection of vulnerable road users improved significantly.
Camera saturation and lens flare can eliminate critical visual information at the worst possible moment.
Sensor degradation over time is an operational edge case. Dirty lenses, calibration drift, and hardware aging gradually reduce system performance.
How Are Edge Cases Detected in Autonomous Driving?
Edge case detection is the process of identifying rare, challenging, or high-uncertainty scenarios in sensor data before they are annotated or used for training. The goal is a prioritized annotation queue that targets the scenarios a model struggles with, rather than labeling data uniformly.
Knowing that edge cases exist is one thing. Finding them systematically in petabytes of driving data is another. Our guide to mining edge cases from fleet data covers the end-to-end process. There are three broad families of detection methods.
Rule-Based Detection
Scenario scripting involves writing queries against structured driving logs. For example: flag any segment where the ego vehicle brakes harder than 0.5g. Flag any segment where a detected object crosses the ego vehicle's predicted path within 2 seconds.
Threshold-based filtering extends this to continuous metrics. Flag any frame where the number of detected objects exceeds a threshold, or where tracker instability is high.
Rule-based methods are transparent and auditable. The limitation is they only find edge cases you can anticipate.
Data-Driven Detection
Anomaly detection in feature space uses the model's own learned representations to identify unusual inputs. Techniques like autoencoders, isolation forests, and density estimation can flag outliers automatically.
Out-of-distribution (OOD) detection specifically targets inputs that differ from the training distribution. Methods like Mahalanobis distance scoring and energy-based models can identify when a model is operating outside its comfort zone.
Uncertainty estimation uses the model's own confidence as a signal. Bayesian neural networks, MC-dropout, and deep ensembles all provide uncertainty estimates. High uncertainty is a strong indicator of an edge case.
Similarity search and scenario retrieval index sensor data as embeddings from a vision, LiDAR or multimodal encoder. Edge cases tend to sit in small clusters or as outliers far from the main clusters, so low-density regions are where to look. The index also works in reverse: given one known edge case, query the full dataset for analogues, and a single novel capture becomes a set of similar scenarios ready for annotation.
Data-driven detectors need calibrating. One that flags too aggressively creates long review queues of false positives. One that is too conservative misses genuine edge cases. Teams tune the threshold on the trade-off between the annotation cost of false positives and the risk of missed edge cases.
Active Learning for Edge Case Discovery
Active learning combines model uncertainty with human expertise in a continuous feedback loop.
Using model confidence to find hard examples means routing low-confidence predictions to human reviewers. Instead of annotating random data, you focus effort on the scenarios where the model struggles.
Disagreement sampling and core-set selection widen the net. Disagreement sampling flags frames where the members of a model ensemble disagree, a sign that the training data covers that region poorly. Core-set selection picks the examples farthest from the current training set in the model's feature space, which targets distribution gaps directly.
Feedback loops between model and annotation create a virtuous cycle. The model identifies what it does not understand. Humans annotate those scenarios. The model retrains and becomes more capable. Its uncertainty shifts to a new frontier of harder cases.
Active learning has one blind spot: it only surfaces scenarios the current model is uncertain about. If the model has learned to ignore a scenario type entirely, or misclassifies it with confidence, uncertainty sampling will not find it. Similarity search and rule-based filters cover that gap, which is why production pipelines combine methods rather than relying on one.
Recent research from NVIDIA's Alpamayo-R1 project demonstrates the impact. A driving model trained with structured reasoning data reached up to a 12% improvement in planning accuracy on challenging cases and a 35% reduction in close encounters in closed-loop simulation, and reinforcement learning post-training improved reasoning quality by 45%. The gains come from what the model is taught, not only from model size.
How Do You Build an Edge Case Dataset for Autonomous Driving?
Mining Real-World Driving Data
The most valuable edge cases come from real driving. Fleet data provides authentic examples of rare scenarios. The challenge is scale: you may need to process millions of miles to find a few thousand meaningful edge cases.
Coverage matters more than volume. A model trained on one million routine frames and 1,000 edge case frames will perform well on routine scenarios and poorly at the edges. A dataset of 100,000 frames with intentional edge case coverage trains a more safety-relevant model. That is why detection comes before annotation: find the rare scenarios first, then spend the labeling budget on them.
Simulation and Synthetic Data
Simulation can generate edge cases on demand. Modern simulation platforms can vary weather, lighting, object appearance, and behavior parametrically. The limitation is the sim-to-real gap. The best approach combines synthetic data for coverage with real data for authenticity.
Prioritizing and Tracking Coverage
Detection produces candidates, and not every candidate is worth the same annotation cost. Prioritize by safety criticality first: road users in potential conflict with the ego vehicle come before an unusual road texture. Then weigh model impact, scenario diversity and coverage gaps. Annotating 100 nearly identical construction zone frames adds less than annotating 20 distinct construction zone configurations. If night-time pedestrian scenarios are underrepresented in your labeled data, that gap outranks adding more examples to a category you already cover.
A scenario ontology with coverage metrics makes this measurable: how many distinct edge case categories have been annotated, how many examples each has, and where gaps remain. Our guide to mining edge cases from fleet data covers ranking candidates by recurrence, severity and annotation yield.
Annotation Requirements for Edge Cases
Edge case annotation demands higher precision than routine labeling:
- Domain experts who understand driving safety, not just general-purpose labelers
- Sensor fusion annotation that combines camera, LiDAR, and radar for complete scene understanding
- Contextual labels that capture not just what is in the scene but why it matters
- Quality assurance workflows with multiple review stages
- Structured reasoning annotations that explain the causal chain from perception to decision
It is not enough to label what objects are present. Models need to understand why a scenario is dangerous and what the correct response is.
Quality matters more here than on routine data. A mislabeled edge case can do more harm in training than a mislabeled routine frame, because the model has less context to recover from the error.
Adverse weather needs its own guideline rules. An instruction like "label every vehicle" is unambiguous on a clear afternoon and means little in fog at 200 meters, because it does not say what counts as seeing a vehicle. Left open, each annotator settles the question in their own consistent but individual way. Before labeling starts, the guideline has to answer three questions: at what point an object is too degraded to label, what evidence justifies inferring an object nobody can see directly, and how an annotator records that they are unsure. Answering them afterwards means relabeling.
Recording uncertainty is better than forcing a choice. If an expert cannot tell whether a shape at the edge of the headlights is a pedestrian or a trash bag, labeling it a pedestrian teaches the model to see things that are not there, and leaving it out teaches the model to ignore ambiguous shapes near the road. Marking it as unresolved keeps both errors out of the training data, and it makes evaluation fairer: a model should not be penalized for missing something no person could identify.
Two practices make the bad-weather data you already have worth more than collecting more of it. Select frames by condition change, sensor disagreement or model uncertainty rather than at fixed intervals, so the short transitions are not skipped. And measure inter-annotator agreement on the adverse-weather subset on its own. Agreement in clear conditions says little, and a sharp drop against the clear-weather baseline means the guideline is underspecified, which no amount of frame-by-frame review will fix.
Kognic's Approach to Edge Case Handling
At Kognic, we have built our annotation platform specifically for the challenges that matter most in autonomous driving, and edge cases sit at the top of that list.
Platform support for complex scenario annotation. Kognic handles the full spectrum: 2D, 3D, sensor fusion, and temporal sequences. For edge cases, annotators work with the complete picture.
Active learning integration. Our platform supports active learning workflows that prioritize the most valuable data for annotation.
Quality assurance for safety-critical labels. Multi-stage review, inter-annotator agreement metrics, and configurable quality gates ensure safety-critical labels meet the required standard. Over 90 automated quality checkers built for autonomous driving data run on every annotation.
Sensor fusion for complete scene understanding. Many edge cases are only understandable when you combine multiple sensor modalities.
Language Grounding for explaining WHY edge cases are dangerous. Kognic's Language Grounding capabilities enable teams to annotate the causal reasoning behind driving decisions: what is happening, why it is dangerous, and what the correct response should be.
Edge cases are not going away. The teams that build systematic, scalable approaches to detecting, annotating, and learning from edge cases are the ones that will ship safe, reliable autonomous systems.
FAQ Section
Q: What is an edge case in autonomous driving?
An edge case is a rare or unexpected driving scenario that falls outside what a self-driving system was trained to handle. Examples include pedestrians in wheelchairs crossing at night, wrong-way cyclists, or sun glare coinciding with a pedestrian crossing. These scenarios are critical because they represent the situations most likely to cause safety failures.
Q: Why are edge cases so dangerous for self-driving cars?
Edge cases are dangerous because autonomous systems perform reliably in normal conditions but can fail unpredictably in scenarios they have not encountered before. A high accuracy score on routine driving does not carry over to the rare scenarios a system has barely seen, and those are where the most serious failures happen.
Q: How many edge cases exist in autonomous driving?
The number is effectively unlimited. Edge cases follow what researchers call the "long tail problem," where rare events are individually uncommon but collectively represent a large portion of real-world risk. New edge cases emerge continuously as driving environments, vehicle types, and road user behaviors change.
Q: What is the difference between an edge case and a corner case?
An edge case is a scenario at the boundary of expected operating conditions, such as heavy fog or an unusual road object. A corner case occurs when multiple edge conditions combine simultaneously, for example, heavy fog plus a wrong-way cyclist plus sensor degradation. Corner cases are rarer and harder to anticipate because they involve compounding factors.
Q: How do companies detect edge cases in driving data?
Three main approaches exist. Rule-based methods use predefined scenario scripts and threshold filters to flag known patterns. Data-driven methods use anomaly detection, out-of-distribution detection, and uncertainty estimation to find scenarios the model struggles with. Active learning combines model uncertainty signals with human expert review to continuously identify new edge cases.
Q: What is the difference between edge case detection and scenario mining?
Edge case detection is the broader process of surfacing rare or uncertain scenarios from a dataset. Scenario mining is a specific technique, typically using embedding-based similarity search, to find clusters of related scenarios or retrieve analogues of a known edge case across a large dataset.
Q: What is active learning in edge case detection?
Active learning selects unlabeled examples for annotation based on model signals rather than at random. Uncertainty sampling picks low-confidence examples, disagreement sampling picks examples where an ensemble of models disagrees, and core-set selection picks examples farthest from the current training data in feature space.
Q: What role does annotation play in handling edge cases?
Annotation is essential because edge cases require human expert judgment to label correctly. Annotators identify what is happening in the scene, classify the type of edge case, and provide contextual reasoning about why it matters. High-quality annotations with causal reasoning labels help models learn not just what objects are present, but why a scenario is dangerous.
Q: Why do autonomous vehicles struggle in rain and snow?
Precipitation degrades each sensor differently. Rain blurs camera images and produces false LiDAR returns from droplets and road spray, while settled snow hides the lane markings and road edges that perception relies on. Because several sensors degrade at the same time, sensor fusion does not fully compensate.
Q: Should annotators label objects they cannot clearly identify?
That decision belongs in the annotation guideline, made once and applied the same way by every annotator, rather than left to each person. The most useful approach is to let annotators record uncertainty explicitly, so the dataset separates an object that was absent from one that could not be resolved.
Ready to tackle the long tail? Learn how Kognic helps autonomous driving teams build edge case datasets with production-grade annotation, active learning, and the quality assurance workflows that safety-critical systems demand.