
Mining Edge Cases from Fleet Data
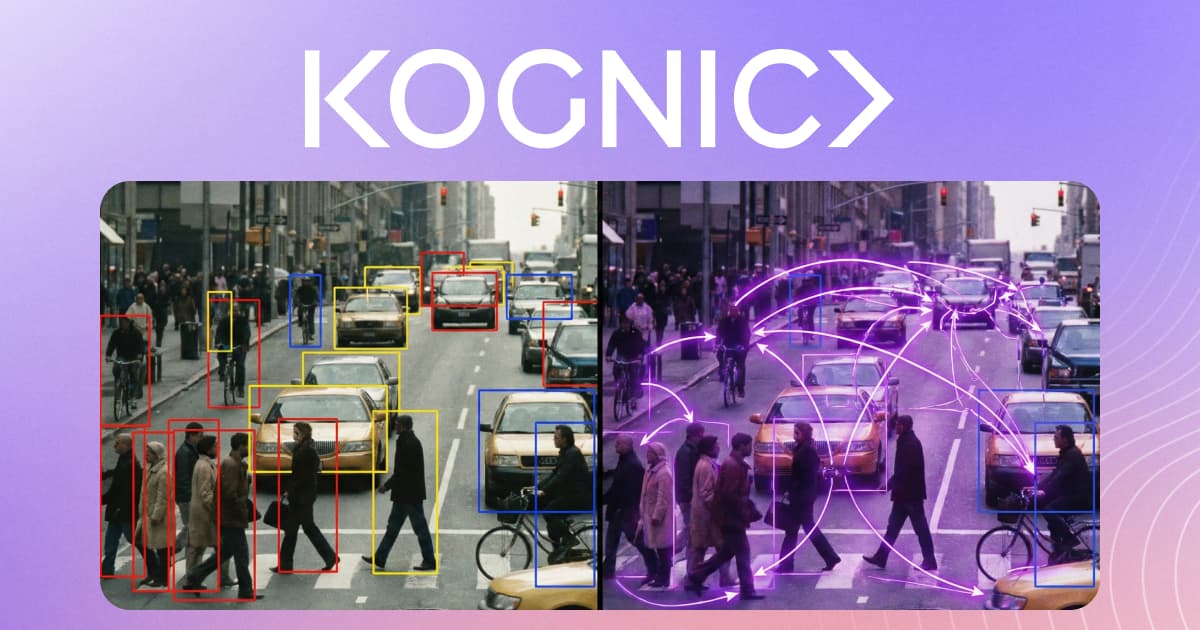
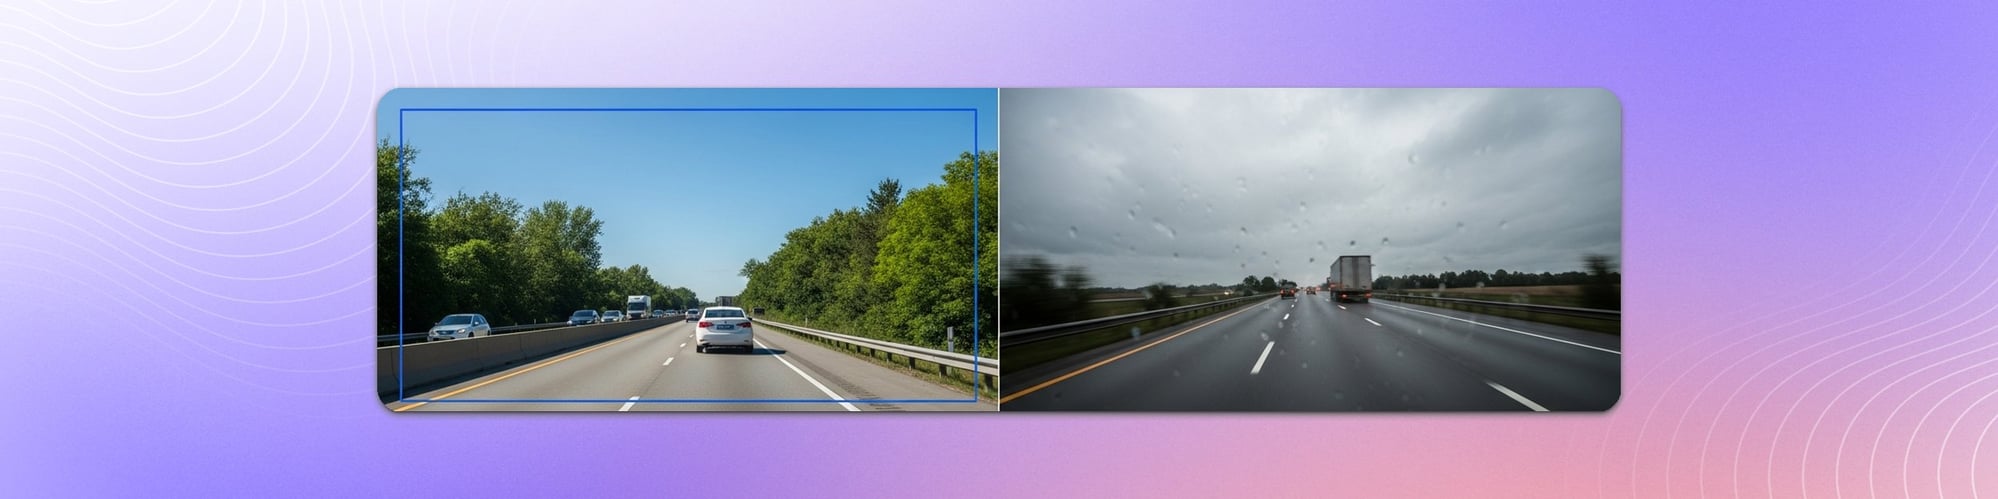
Your fleet drives a million miles and collects terabytes of sensor data. Almost all of it looks like the previous million miles: highway cruising in good weather, urban intersections in daylight, predictable pedestrian behavior. The small share that does not look like the rest is where your model breaks.
Finding that small share is edge case mining. This post covers the methods, the taxonomy, and the operational pipeline for turning raw fleet data into annotated training data that addresses the failure modes that actually matter.
The Fleet Data Opportunity
Every mile driven by an AV or ADAS-equipped vehicle generates sensor data. Most of it sits in storage and is never examined. The problem is not a shortage of data. The problem is that the scenarios that cause model failures are rare, unevenly distributed across the fleet, and do not announce themselves.
A single autonomous vehicle can generate up to 4TB of raw sensor data per day.1 Left unmined, these scenarios compound in storage. Systematically processed, they become the training signal that closes the gap between a model that works in testing and one that holds up in production.
That is one vehicle. Most AD and ADAS teams collect data with test fleets of tens or hundreds of vehicles. When collection moves to a customer fleet, the data volume does not just grow, it explodes. At that scale you cannot keep everything and you cannot label everything. You have to curate ruthlessly.
The economic argument is straightforward. Targeted annotation of high-impact edge cases produces more model improvement per annotation dollar than random sampling of the full data pool. The cost is building the pipeline to identify, classify, and prioritize which scenarios deserve the annotation budget.
Think about how you would teach a person to drive. You would not show them 10,000 hours of random highway footage and hope they work it out. You would pick the experiences: parallel parking, merging into traffic, recognizing when a pedestrian is about to cross. Edge case mining brings the same intent to model training. The question stops being "what data do we have?" and becomes "what data do we need?"
What Makes a Good Edge Case?
Not every rare event is a useful edge case. A good edge case has three properties.
Model failure or near-failure. The scenario produces low confidence, incorrect output, or downstream planning behavior that should not have happened. Rarity alone is not sufficient. A blue fire hydrant is rare, but if your model handles it correctly, there is nothing to learn from it.
Reproducibility. The failure repeats across conditions, sensor positions, or locations. Reproducibility separates systematic model weaknesses from one-off sensor noise. A single anomalous frame in 50,000 is worth studying. A pattern of the same failure in specific lighting conditions is worth annotating at scale.
Annotability. The scenario can be labeled with sufficient accuracy and consistency to produce a useful training signal. A frame completely obscured by rain is not annotable. A frame where rain partially obscures a pedestrian who is still classifiable by a domain expert is.
Scenarios that meet all three criteria are worth full annotation throughput. Those that meet only one or two are useful for ontology development but may not justify the annotation cost.
Automated Edge Case Detection Methods
Manual review of fleet footage at scale is not viable. Finding edge cases requires automated detectors that flag candidate scenarios for human triage.
Uncertainty sampling. Run the production model over fleet data and flag frames where confidence falls below a threshold. Low confidence is a proxy for novel input. The limitation: uncertainty sampling conflates genuine edge cases with sensor noise and out-of-distribution non-events that are not safety-relevant.
Prediction disagreement. Run an ensemble of models, or compare outputs against a secondary system. Disagreement between models on the same input indicates a scenario where no single model is confident. Disagreement sampling surfaces different failure modes than uncertainty sampling and is useful when multiple models are deployed in the stack.
Behavior-triggered mining. Use logged vehicle behavior as the signal. Hard braking, steering corrections, disengagements, and planned intervention markers all indicate moments where the system encountered something outside normal operating range. Behavior-triggered mining is high precision: the vehicle already flagged the scenario as worth examining.
Embedding-space anomaly detection. Train a representation model on the full data distribution and flag inputs that fall far from the cluster centers. This finds novel visual scenarios regardless of model behavior, which is useful for proactively expanding the training distribution before failures occur in production.
Cross-sensor inconsistency detection. Flag frames where camera and LiDAR produce inconsistent classifications. A pedestrian detected by camera but absent from the LiDAR point cloud is a candidate for review. Cross-sensor disagreement catches both annotation gaps and sensor fusion failures in the same pass.
Metadata and prompt-based search. Filter fleet logs in the cloud on metadata such as location and weather, then search what remains with a vision-language model or an offline perception stack. Ranking the top N results by similarity to a text prompt works for simple concepts, such as "a red truck". It breaks on the compositional queries the long tail is made of. Ask for "a crossing where the light has just turned green for vehicles and a pedestrian starts to cross too late", and the top results are full of green lights and full of pedestrians, with very few frames where both happen at once. Sent straight to annotation, that noise spends the labeling budget on data that does not improve the model.
No single detector finds everything. Uncertainty sampling misses scenarios where the model is confidently wrong. Behavior-triggered mining misses novel scenarios that have not yet caused failures but will as the ODD expands. Production pipelines combine several of these methods, each tuned to surface a different class of failure.
Scenario Classification and Taxonomy
Raw edge case candidates are unstructured. Prioritizing annotation requires a taxonomy.
A practical taxonomy organizes scenarios across four dimensions.
Trigger type: Weather conditions (rain, fog, snow, direct glare), lighting transitions (night, dawn, tunnel entry and exit), dynamic actor behavior (jaywalking pedestrian, wrong-way cyclist, stationary vehicle in lane), infrastructure anomaly (construction zone, road debris, temporary traffic control).
Sensor condition: Which sensors were affected and how. Camera occlusion, LiDAR return degradation in precipitation, radar interference, multi-sensor disagreement on the same object.
ODD relevance: Does this scenario occur within the operational design domain, or does it represent an ODD boundary condition? Boundary cases may require a policy decision before annotation investment is justified.
Failure mode: What did the model do wrong. False negative, false positive, classification error, trajectory prediction error, or planning failure triggered by an upstream perception mistake.
Classifying across these dimensions tells you whether you are looking at a sensor problem, an ontology gap, a data coverage problem, or a model architecture limitation. Each diagnosis suggests a different response. Mixing them in an undifferentiated annotation queue dilutes the training signal.
Prioritizing Edge Cases by Safety Impact
More edge cases exist than any team has budget to annotate. Prioritization is a safety argument with cost constraints.
The standard framework maps two axes: probability of recurrence and severity of consequences. High probability, high severity scenarios are annotated first. Low probability, low severity scenarios are studied but deferred.
Probability of recurrence is estimated from fleet occurrence rates stratified by geography, time of day, and season. A failure mode that appears once in 10,000 miles in one city may appear once in 200 miles in another. Fleet-wide rates obscure this variation. Geography-stratified occurrence rates support more accurate prioritization.
Severity is evaluated against the planner's downstream response. A misclassified construction barrel at highway speed carries different consequences than the same misclassification in a parking lot at 5 km/h. The model failure is identical. The safety impact is not.
A third factor is annotation yield: how many unique training examples does a scenario type produce per 100 candidate frames reviewed. Some failures are common but visually repetitive. Annotating the 200th version of the same sun-glare misclassification returns diminishing value. Tracking yield prevents over-investment in saturated failure modes while ensuring coverage of the long tail.
From Raw Fleet Data to Annotated Training Data
Mining identifies candidates. Annotation converts them into training data. The conversion is not automatic.
Data preparation. Raw fleet logs are large and often incomplete. Preparation involves extracting relevant frames or sequences, aligning camera and LiDAR timestamps, verifying sensor calibration parameters, and removing frames too degraded to annotate. A fraction of flagged candidates drop out at this stage before any annotation begins.
Briefing annotators on novel scenarios. Edge cases by definition fall outside the standard annotation brief. Each new scenario type requires updated guidelines with concrete visual or point-cloud examples before annotation begins. The brief must specify: what is the correct label, how should boundary cases be handled, and what does acceptable inter-annotator agreement look like.
Annotation with specialist review. Edge cases warrant a higher review tier than bulk annotation of common scenarios. Frames that are ambiguous, multi-sensor, or involve rare classes should pass through a specialist reviewer before entering the training set. The cost of a labeling error on a rare scenario is higher than on a common one, because the rare label appears infrequently and carries disproportionate weight in training.
Quality verification before ingestion. Automated quality checks should run on edge case annotations before they reach the training set. Standard checks for boundary precision, class distribution, and temporal consistency apply. Additional checks verify conformance to the ontology extensions created for the new scenario type.
Mining the Data You Have Already Labeled
Edge case mining usually points at raw fleet logs. The same methods apply to datasets you have already annotated, and those datasets lose value faster than most teams plan for.
Data has a short half-life. Camera suppliers discontinue models. LiDAR resolution becomes outdated. Scope extends to objects that were previously out of scope, and new objects appear on the road: people in masks during Covid, e-scooters, delivery bots, robotaxis. Every static dataset drifts as the world changes.
Your understanding of what the model needs drifts too. Early on, more labeled examples improve perception. Then returns diminish: 500,000 more labeled cars will not improve your recall for lost cargo, and you cannot map your long tail until you are deep into development. A dataset specified entirely upfront overspends on needs that were overestimated and leaves gaps where the unexpected turned out to matter. Sourcing requests that spell out data needs four years ahead, over thousands of spreadsheet lines, routinely lose hundreds of those lines before the proposals are even due.
Treat the dataset as something under development, like the code. Run your current model over it and compare its predictions with the ground truth. When a model that performs well disagrees with a label at high confidence, the label is often the mistake. Objects the model detects that are missing from the annotations point to missed labels. Send those items for correction, so the dataset is updated rather than re-annotated from scratch.
Some disagreements are decisions, not errors. A pedestrian on a billboard is obviously not a pedestrian to a person, but it may not be obvious to the model. You can leave it unannotated and let the model detect it as a pedestrian, or annotate it so the model is not penalized for detecting it. Either way the guideline changes, and the dataset has to follow.
Building a Continuous Mining Pipeline
One-time edge case mining is useful. Continuous mining is what improves a model as the ODD expands.
A continuous pipeline has four operational components.
Automated triggering. The fleet logs data continuously. Detectors run on incoming data and emit candidates whenever a trigger condition fires. Human reviewers evaluate flagged output rather than watching the raw stream.
Triage queue. Flagged candidates enter a triage queue where a reviewer confirms the classification and assigns it to the appropriate scenario type. Triage is the quality gate between raw detector output and the annotation queue. It is also where the taxonomy is maintained and refined as new failure modes appear.
Triage runs best as a fast, high-throughput human filter: a reviewer answers a few binary questions about each candidate, such as "has the light just turned green?" and "is a pedestrian entering the crossing?", and discards the false positives. That lets you run the detectors with a much wider net, because a person removes the noise before it reaches the expensive labeling queue. Your model trains only on the scenarios you intended, and you stop paying full annotation cost for scenarios that turned out to be irrelevant.
Some candidates need more than a yes or no. Was the driver takeover a reaction to a system failure, or simply nervous driving? What does a near-miss look like in this specific ODD? These are forensic questions rather than labeling tasks. A domain expert in the selection loop catches scenarios an explicit query would miss, so you train on what you need to fix, not only on what you knew to look for.
Annotation throughput matched to triage output. The bottleneck in most programs is triage, not annotation. If triage produces 400 reviewed candidates per week, the annotation pipeline should process 400 frames per week. Mismatching throughput creates backlog in one direction or idle capacity in the other.
Feedback loop to detectors. Every annotated edge case provides a label that can improve the detectors themselves. A scenario type previously found only by behavior-triggered mining can train a dedicated detector once enough labeled examples exist. The detector improves, the mining rate for that scenario type improves. Over time, the pipeline becomes self-reinforcing.
This is what separates a fleet with a data strategy from one with a data storage problem. The scenarios that will determine whether the next ODD expansion succeeds are already in your logs. The question is whether your pipeline finds them before your model encounters them in production.
Where Kognic Fits
Kognic's annotation platform handles the annotation step of this pipeline: converting mined edge case candidates into training-ready labeled data across 2D images and 3D point clouds.
Edge case annotation requires rapid brief updates when a new scenario type enters the queue, specialist review for ambiguous or rare frames, and quality checks that extend to the ontology extensions created for novel scenarios. Pre-labeling with human-in-the-loop review reduces annotation time by up to 68% on scenarios where the model already has partial coverage, while 90+ automated quality checkers built for AV data verify boundary precision, temporal consistency, and cross-sensor consistency on every batch.
A large domain-trained annotator workforce and 100 million annotations delivered mean the operational infrastructure for handling rare and novel scenario types is already in place.
For teams scaling a continuous mining pipeline, see how Kognic approaches edge case detection and handling, or contact us to discuss the specifics of your program.
Frequently Asked Questions
What is edge case mining in autonomous driving? Edge case mining is the process of systematically identifying rare or model-challenging scenarios from fleet sensor data, classifying them, and routing them into annotation workflows. The goal is to close the gap between what a model has been trained on and the full range of scenarios it will encounter in production.
How do AV teams find edge cases in fleet data? Teams combine automated detection methods: uncertainty sampling (flagging low-confidence model outputs), behavior-triggered mining (using hard-braking or disengagement events), embedding-space anomaly detection (finding scenarios far from the normal data distribution), and cross-sensor inconsistency detection. No single method finds everything; production pipelines use several together.
What makes a fleet scenario worth annotating? Three properties matter: model failure or near-failure on that scenario, reproducibility across conditions (not a one-off artifact), and annotability. The scenario must be labelable accurately enough to produce a useful training signal.
How do teams prioritize which edge cases to annotate first? By mapping two axes: probability of recurrence in deployment and severity of consequences if the model fails. High probability, high severity scenarios are annotated first. Annotation yield (how many distinct training examples a scenario type produces per batch) is tracked to avoid over-investing in visually repetitive failure modes.
What is a continuous edge case mining pipeline? A pipeline where automated detectors run continuously on incoming fleet data, flagged candidates enter a triage queue for human review, reviewed candidates flow into annotation, and annotated data feeds back to improve the detectors. The loop runs continuously rather than as a one-time project.
Can a vision-language model find edge cases in fleet data on its own? It helps with recall more than precision. Prompt-based similarity search finds simple concepts well but returns many partial matches for compositional scenarios, such as a green light and a late-crossing pedestrian in the same frame. Teams cast a wide net with the model, then use a fast human filter to discard false positives before anything reaches full annotation.
Should an existing dataset be re-annotated when requirements change? Usually not from scratch. Run the current model over the labeled data, compare its predictions with the ground truth to find likely label errors and missed objects, and send only those items for correction. Treating the dataset as something under development, like code, keeps it useful as sensors, scope and guidelines change.
-
Based on Intel's estimate for a vehicle equipped with cameras, radar, sonar, LiDAR, and GPU generating approximately 131MB/s. Across a 10-hour driving day, this amounts to ~4.7TB. Via Premio Inc: Autonomous Vehicle Data Storage. ↩
Share this
Written by